EgoHAnG: Graph-Enhanced Horizon Aware
Egocentric Action Anticipation
Abstract
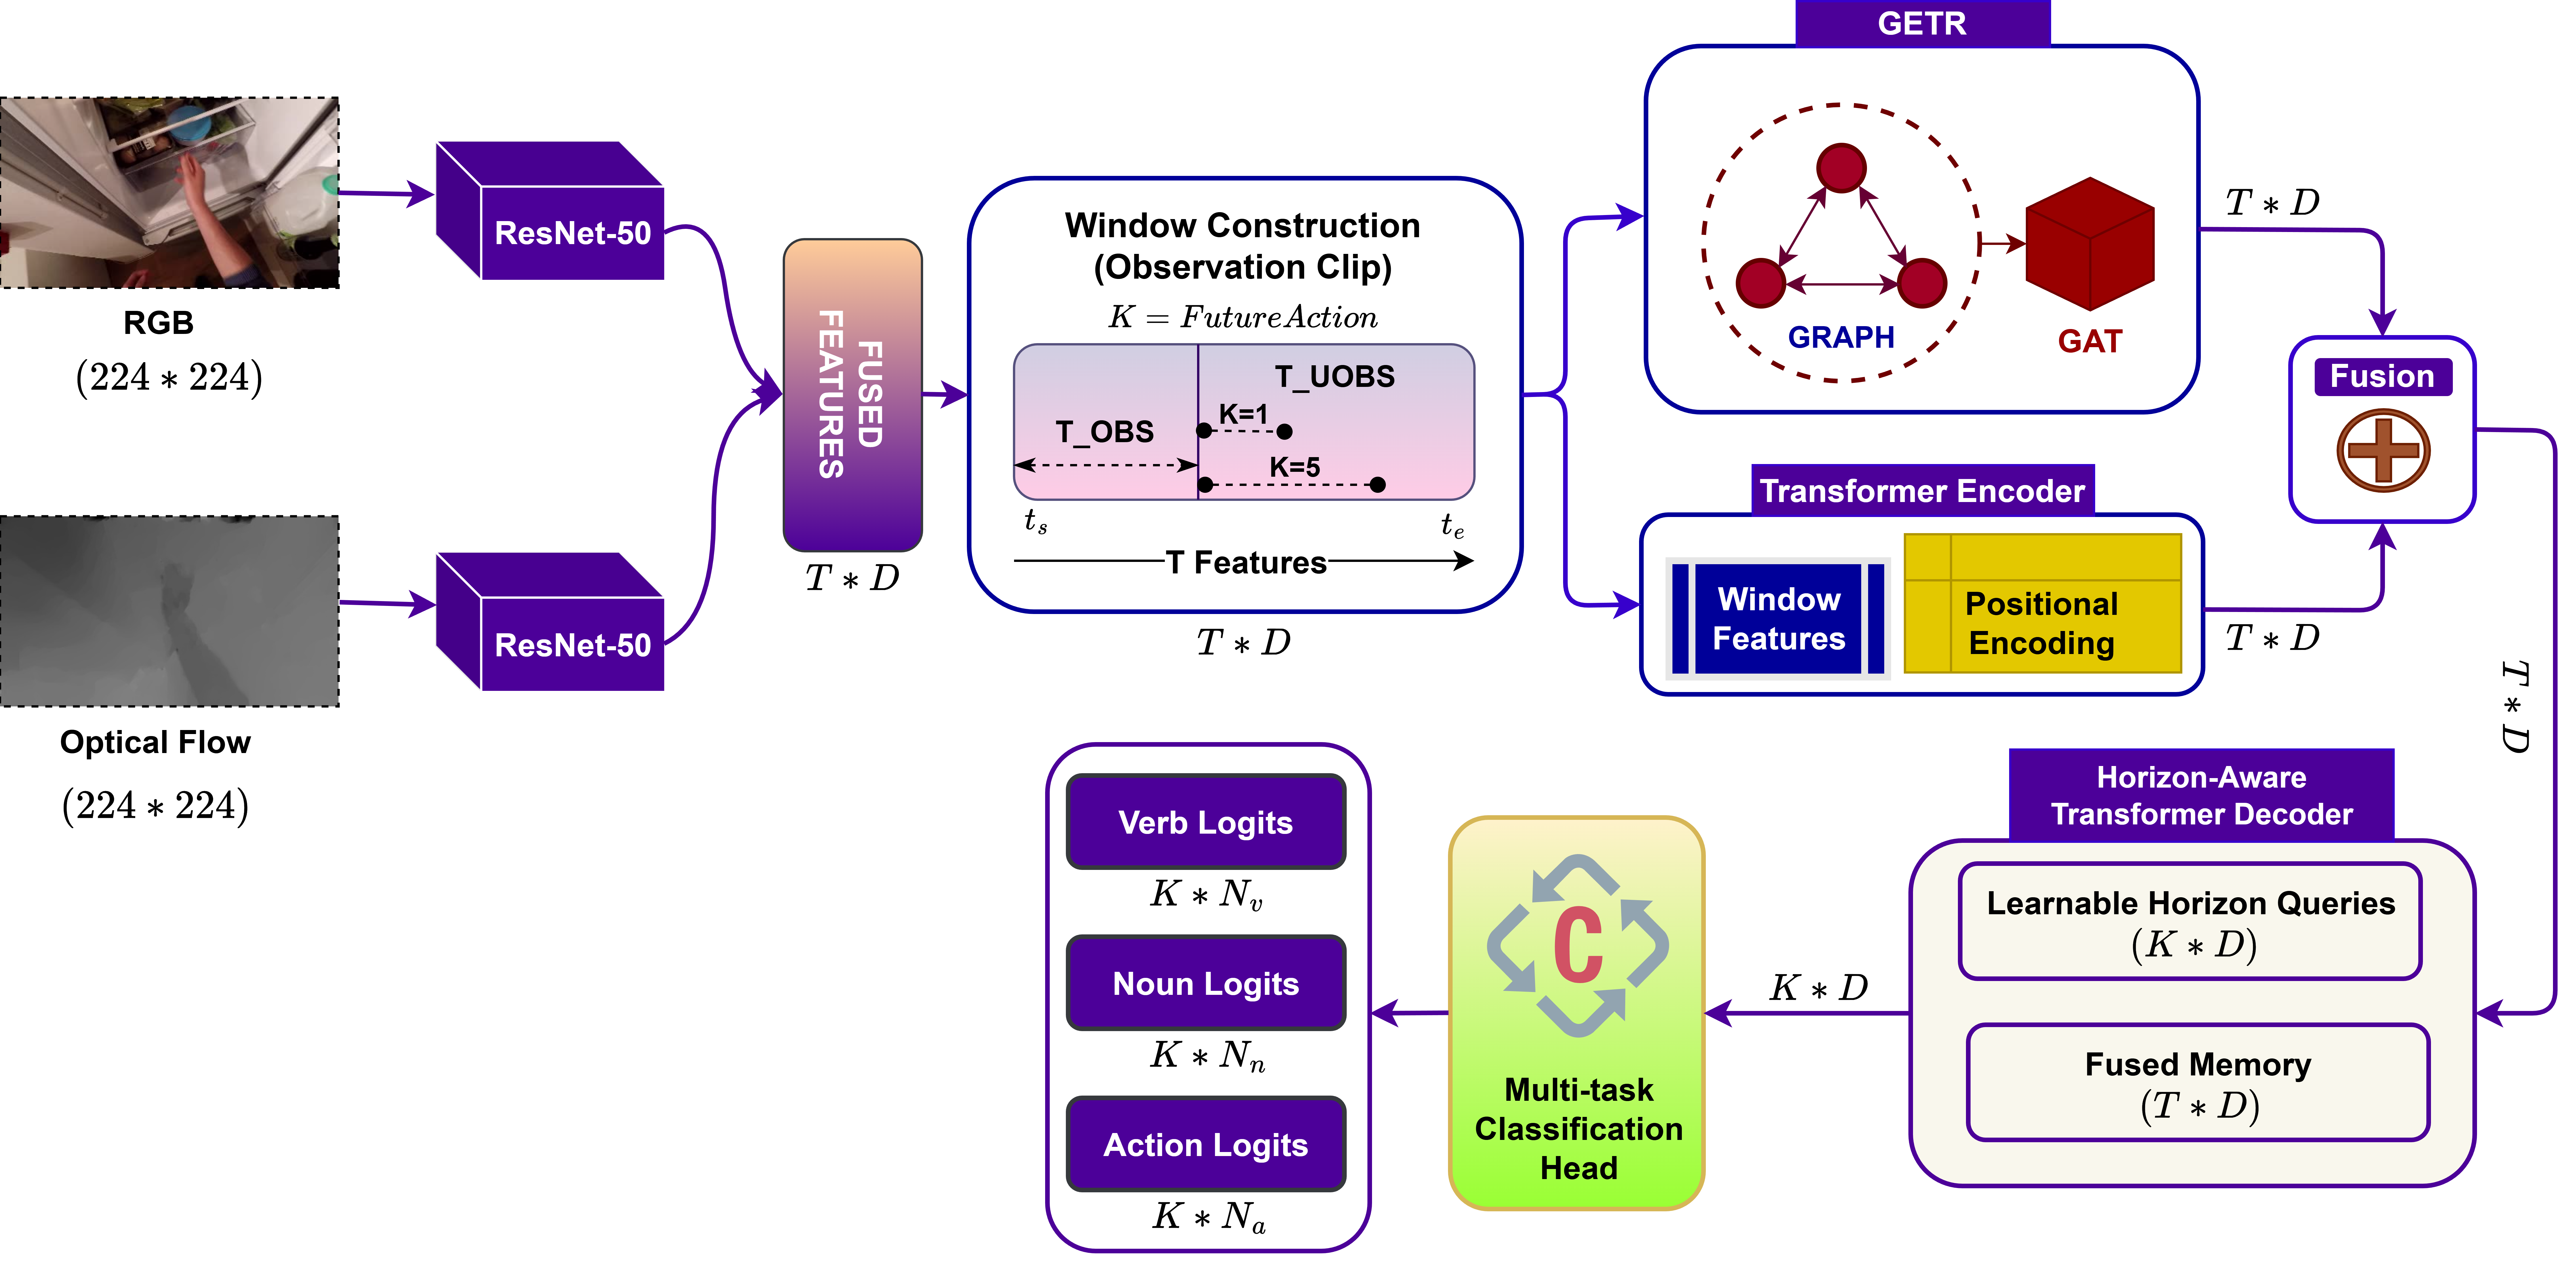
Egocentric action anticipation has become an increasingly popular topic in computer vision. Most existing state-of-the-art action anticipation approaches rely on multi-modal feature fusion and predominantly employ architectures such as 3D CNNs, LSTM, RULSTM, I3D, X3D-XS, lightweight models, and more recently, Transformer-based methods. However, most existing solutions rely primarily on sequential modeling, which often struggles to capture complex inter-frame relationships and fails to effectively handle short-, mid-, and long-term cues appearing at different times in the future. In this paper, we propose EgoHAnG (Egocentric Horizon Aware Action Anticipation using Graphs), an end-to-end framework that integrates multimodal fusion with graph-based relational reasoning and Transformer-based temporal modeling. Our approach first performs early fusion of RGB and optical-flow features using a pretrained ResNet-50 to capture complementary appearance and motion cues. We then construct a dynamic k-NN graph over the observed frames and apply graph-based attention to model inter-frame relational structures, enabling robust capture of long-range temporal dependencies in egocentric videos. Finally, we introduce a horizon-aware decoder with learnable horizon queries to independently predict verb, noun, and action labels across multiple anticipation horizons, improving both short- and long-term action anticipation. Experimental evaluations on EPIC-Kitchens and EGTEA Gaze+ demonstrate that the proposed method improves Top-5 action recall by 1.1% and 3.73%, respectively, over current state-of-the-art methods.
Method Overview
EgoHAnG combines early RGB–optical-flow fusion, Graph-Enhanced Temporal Reasoning (GETR), and a Horizon-Aware Transformer Decoder (HATD). GETR couples similarity-based graph attention with ordered temporal encoding, while learnable horizon queries extract future evidence specific to each anticipation time.
Qualitative Results
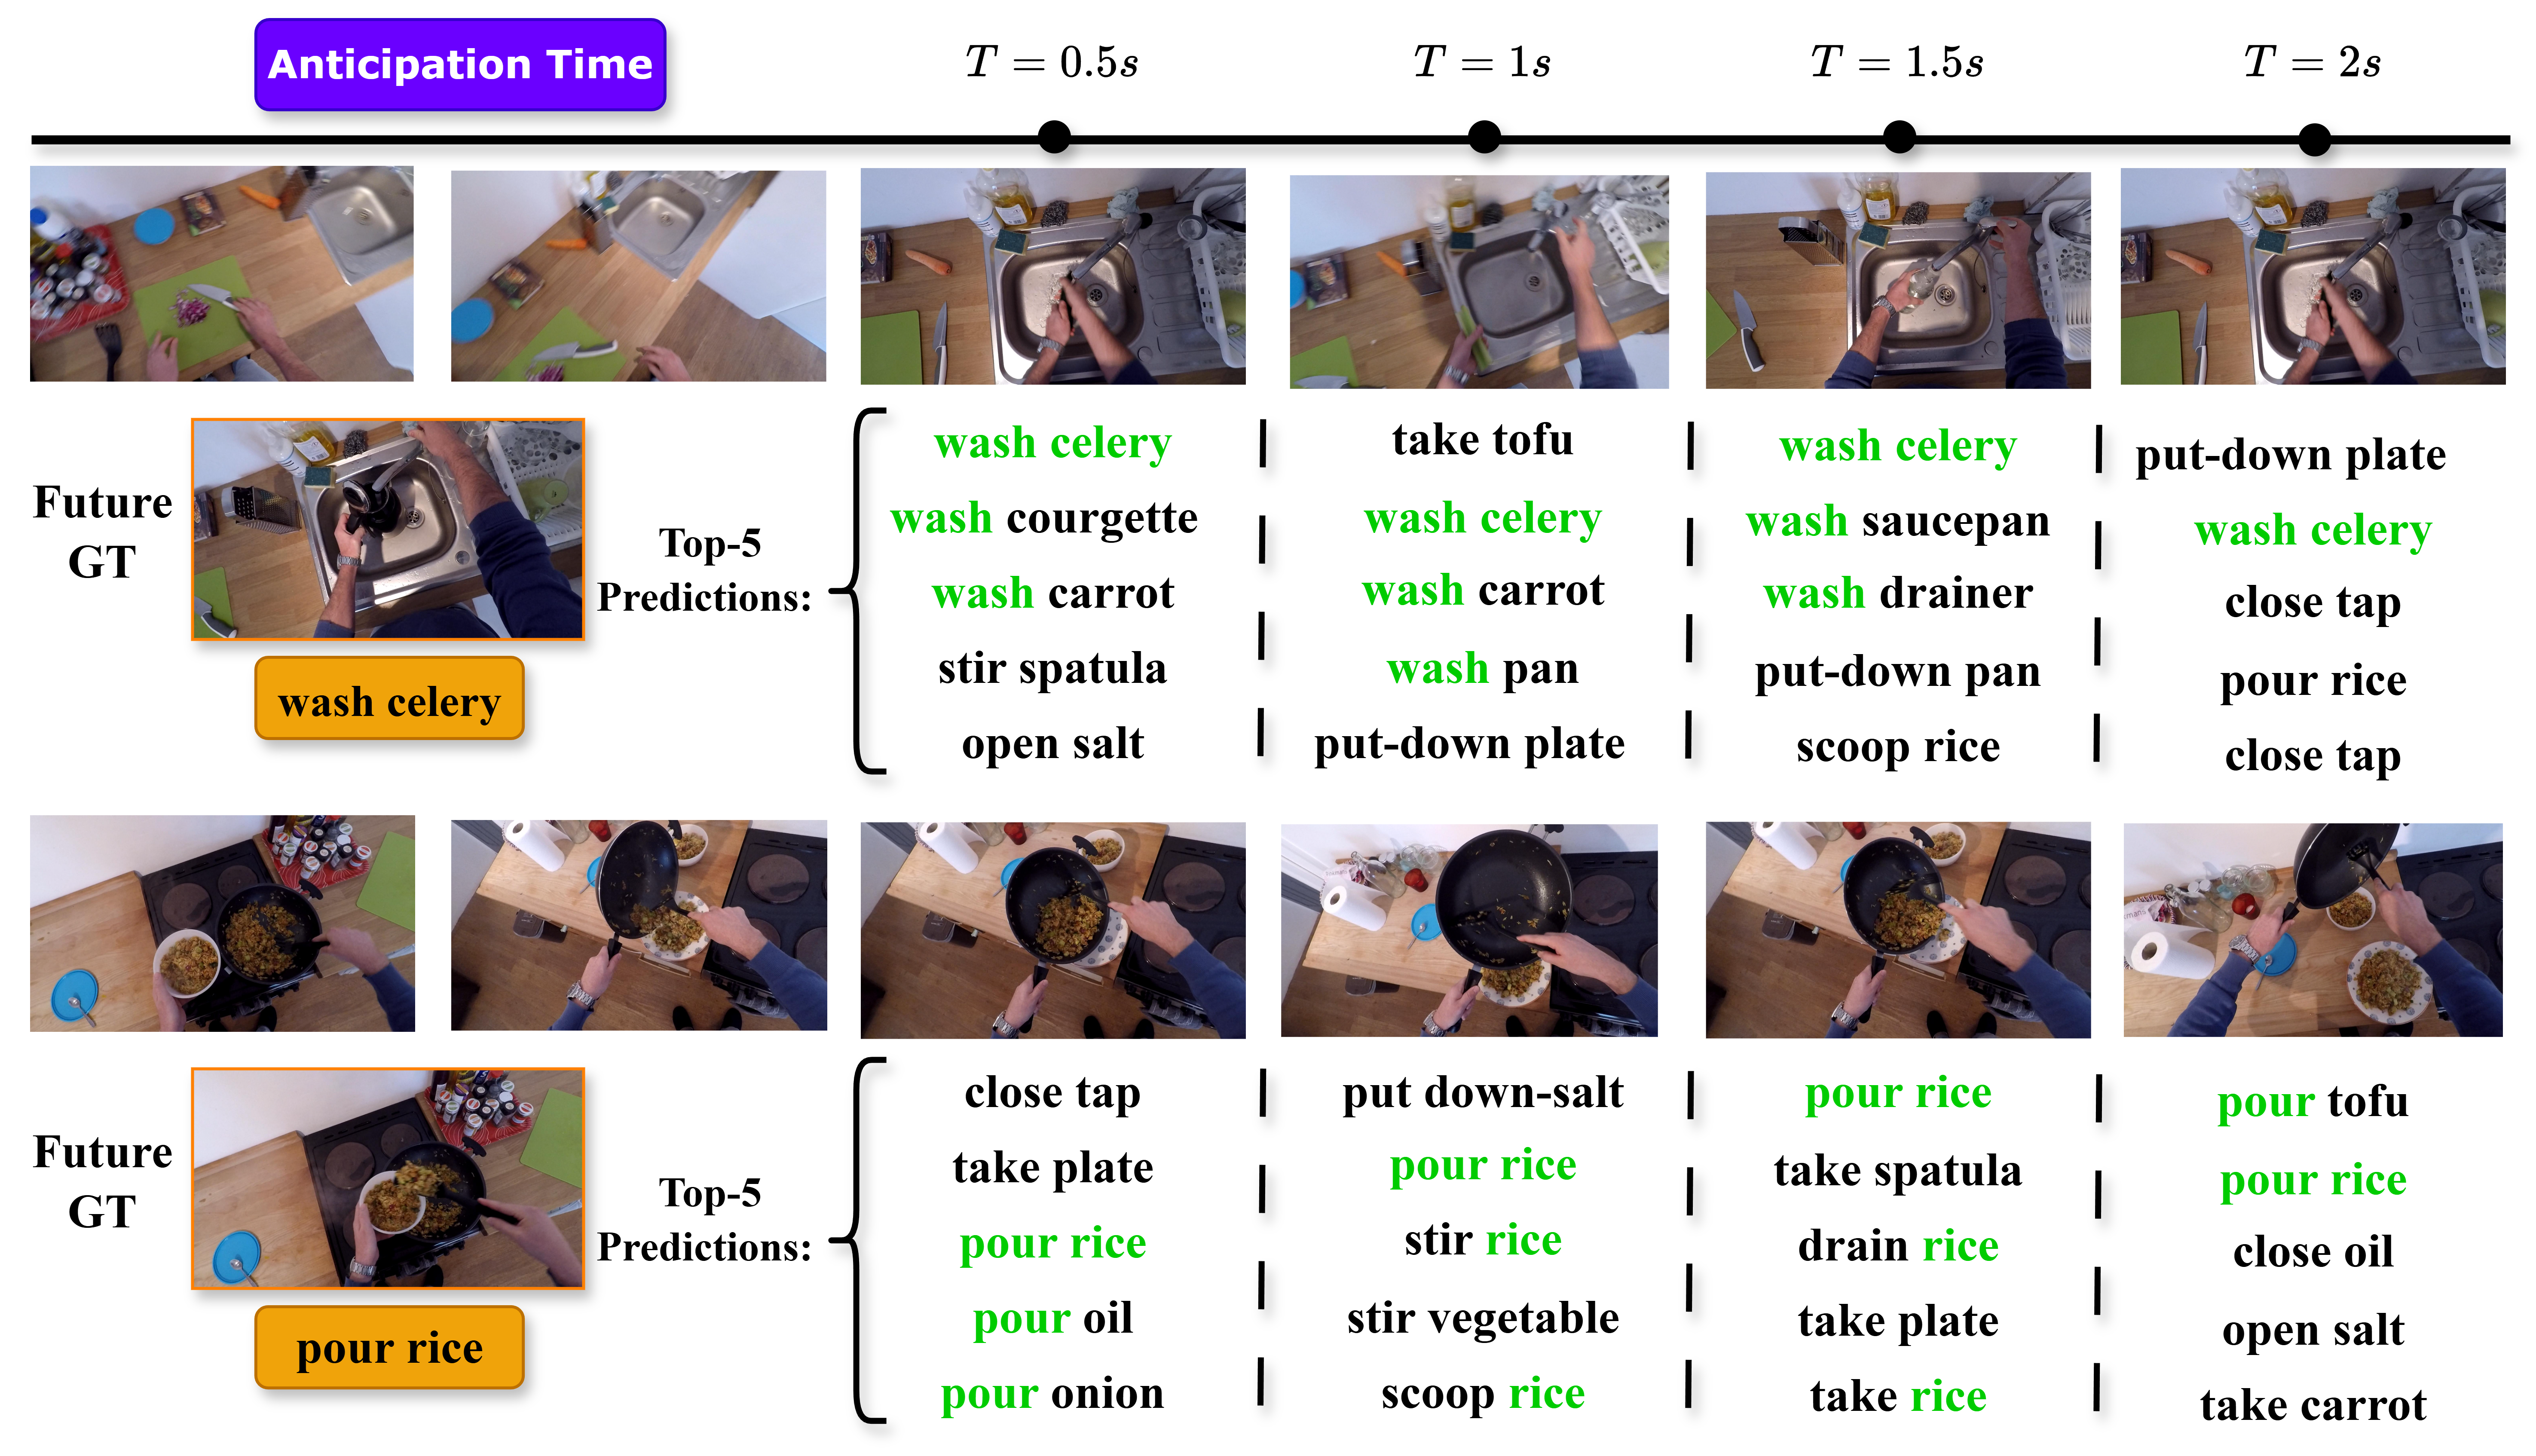
Top-5 action predictions at multiple anticipation horizons. Correct predictions are highlighted in green, demonstrating how EgoHAnG remains effective from short to long anticipation times.
Results
Paper & Code
Pawanesh Kumar Vishwakarma, Ananda S. Chowdhury, and Abhimanyu Sahu
EgoHAnG: Graph-Enhanced Horizon Aware Egocentric Action Anticipation
ICPR, 2026